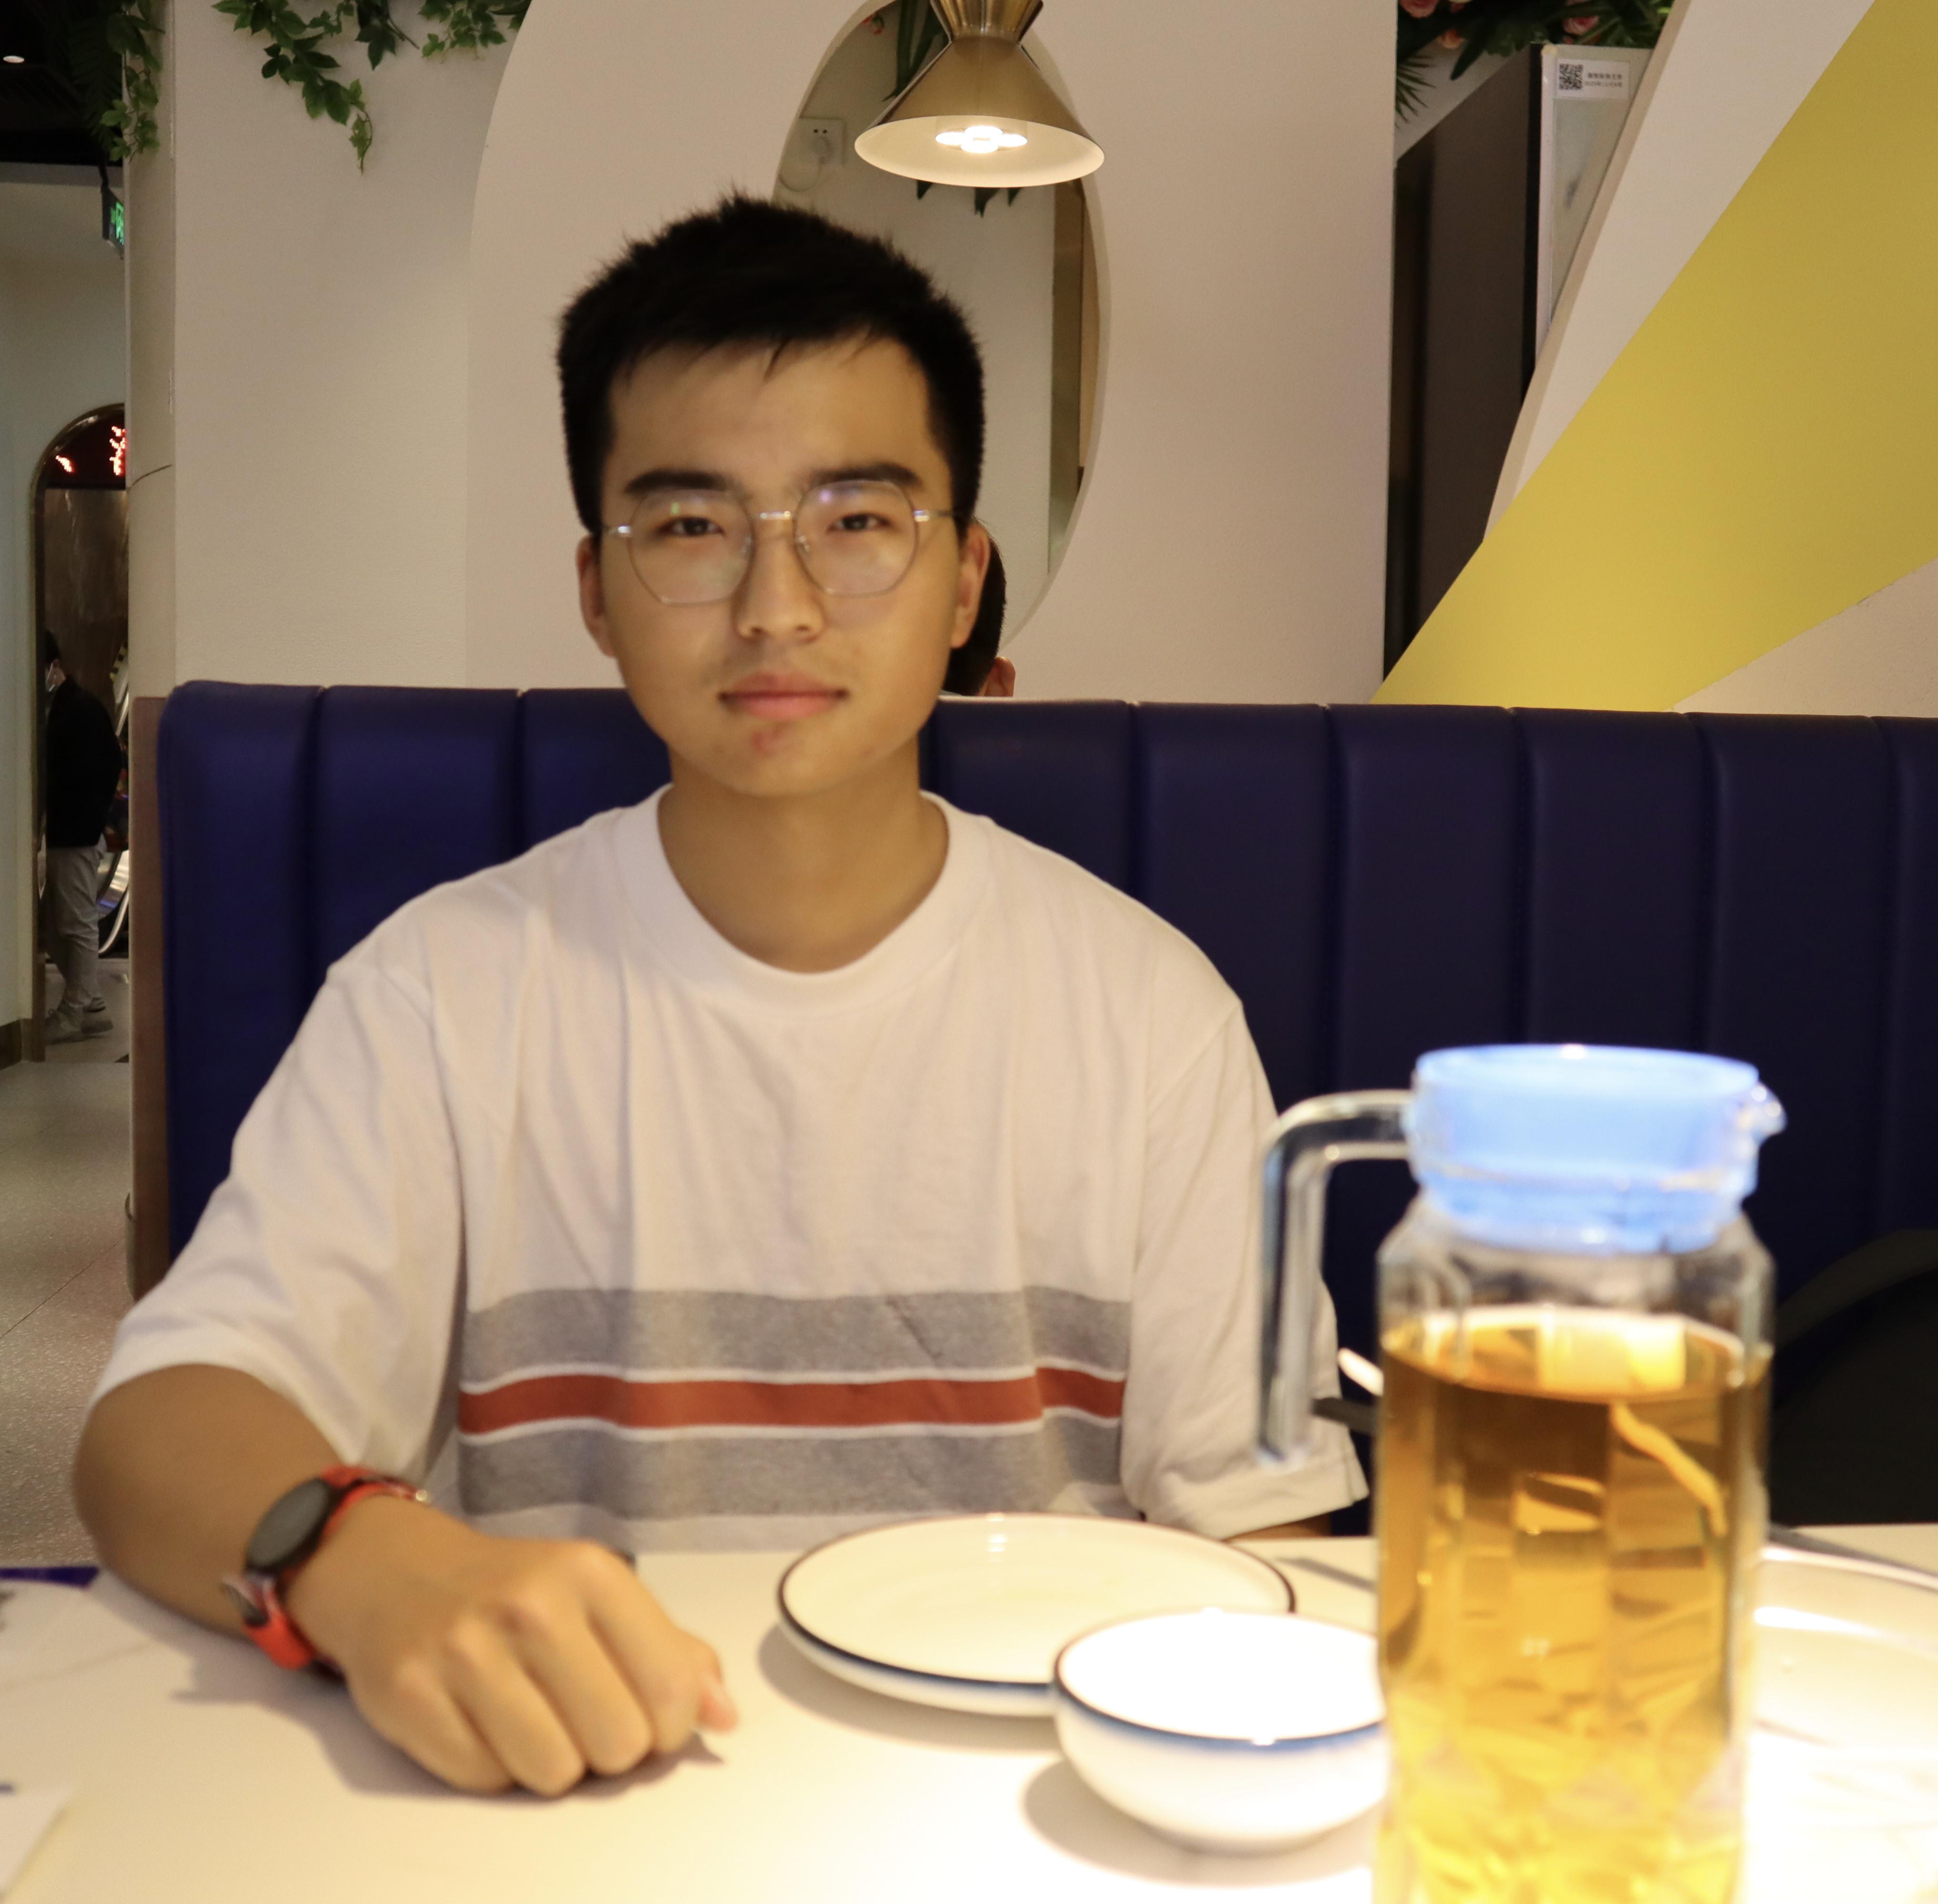
Hi, I am Yihang Zuo, a PhD student at Arizona State University advised by Prof. Deliang Fan. Previously, I received my M.S. degree from The Hong Kong University of Science and Technology (Guangzhou) co-advised by Prof. Yuzhe Ma and Prof. Jiayi Huang, and B.S. degree from South China University of Technology. I have interned at the Shanghai AI Laboratory under the guidance of Prof. Zhuolun He and Prof. Bei Yu.
My research interests include KV Cache Optimization, AI accelerator, Design Space Exploration, Efficient AI, and EDA.
I'm always happy to connect and discuss possible collaborations. Please don't hesitate to contact me if you're interested in related topics.
Warning
Problem: The current name of your GitHub Pages repository ("Solution: Please consider renaming the repository to "
http://".
However, if the current repository name is intended, you can ignore this message by removing "{% include widgets/debug_repo_name.html %}" in index.html.
Action required
Problem: The current root path of this site is "baseurl ("_config.yml.
Solution: Please set the
baseurl in _config.yml to "Education
-
 Arizona State UniversityPh.D. Student in Electrical and Computer EngineeringSep. 2025 - present
-
 The Hong Kong University of Science and Technology (Guangzhou)M.Phil. in MicroelectronicsSep. 2023 - Aug. 2025
-
 South China University of TechnologyB.Eng. in Microelectronics Science and EngineeringSep. 2019 - Jun. 2023
Academic Services
-
ASPDAC /DATE /DAC Reviewer2025
-
JETCAS/AAAI/DATE/ACL Reviewer2026
Experience
-
 Shanghai Artificial Intelligence LaboratoryResearch InternSep. 2022 - Mar. 2023
-
 University of Illinois Urbana-ChampaignSummer SessionAug. 2021
Honors & Awards
-
1st Prize in Guangdong province, China Undergraduate MCMOct. 2020
-
1st Prize in South China, China college IC competitionJul. 2022
-
2nd Prize in Guangdong province, China Undergraduate MCMOct. 2021
-
3rd Prize in South China, China college IC competitionJul. 2021
-
3rd Prize, China college IC competitionAug. 2022
-
Runner-up in the SCUT debate competitionNov. 2020
-
Meritorious winner, Mathematical Contest in Modeling (MCM)Feb. 2021
News
Selected Publications (view all )
LUMOS: A Monolithic 3D 2T0C MoS₂ eDRAM-based Lookup Table CIM Accelerator with Dual-Side Compression
Design, Automation & Test in Europe Conference (DATE) 2027
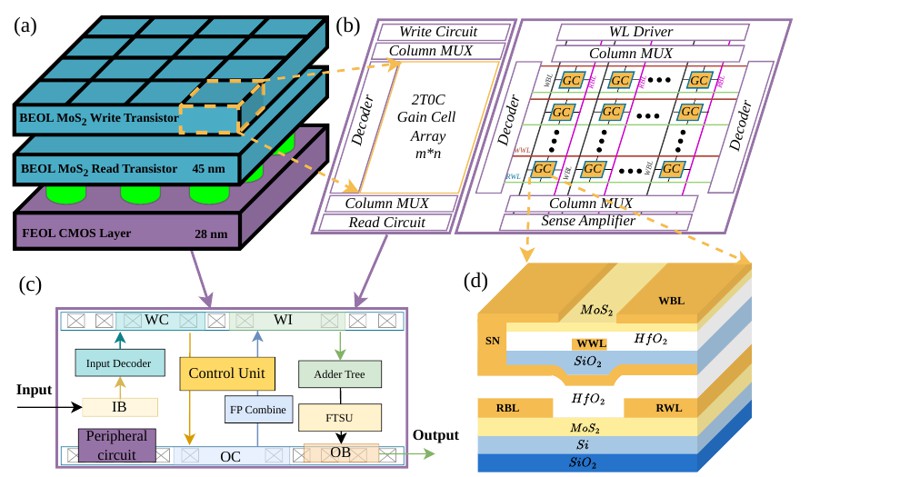
Digital compute-in-memory (DCIM) accelerators improve the energy efficiency of large language model (LLM) inference by placing the computing logic within the memory array. However, existing DCIM designs share three limitations in LLM inference: a large, energy-hungry adder tree, a mismatch with the matrix-vector multiplication (GEMV) in the decoding phase, and limited on-chip capacity. This paper presents LUMOS, a monolithic 3D 2T0C MoS₂ eDRAM-based lookup table (LUT) accelerator with dual-side compression, co-designed across the device, algorithm, and architecture levels. At the device level, we fabricate MoS₂ transistors and calibrate a SPICE model against their measured characteristics; the resulting cell and array simulations show high density, low access energy, and long retention. At the algorithm level, LUMOS compresses the weights via vector quantization (VQ), which also reformulates decoding from GEMV to matrix multiplication, and applies 4:8-structured input sparsity to reduce bandwidth and memory demand. At the architecture level, every multiplication becomes a table lookup followed by a shallow adder tree, and the working set of a layer stays on the die. LUMOS achieves 37.7 TFLOPS/W and 9.59 MB/mm² effective on-die memory density, 1.91×–8.51× more energy-efficient than state-of-the-art DCIM macros. By holding a Qwen3-30B-A3B block on 38 cores, it decodes with zero off-chip weight traffic, 10.4× faster and 275× more energy-efficiently than the streaming VQ accelerator EVA on the same 2-bit model.
Read more
LUMOS: A Monolithic 3D 2T0C MoS₂ eDRAM-based Lookup Table CIM Accelerator with Dual-Side Compression
Design, Automation & Test in Europe Conference (DATE) 2027
Digital compute-in-memory (DCIM) accelerators improve the energy efficiency of large language model (LLM) inference by placing the computing logic within the memory array. However, existing DCIM designs share three limitations in LLM inference: a large, energy-hungry adder tree, a mismatch with the matrix-vector multiplication (GEMV) in the decoding phase, and limited on-chip capacity. This paper presents LUMOS, a monolithic 3D 2T0C MoS₂ eDRAM-based lookup table (LUT) accelerator with dual-side compression, co-designed across the device, algorithm, and architecture levels. At the device level, we fabricate MoS₂ transistors and calibrate a SPICE model against their measured characteristics; the resulting cell and array simulations show high density, low access energy, and long retention. At the algorithm level, LUMOS compresses the weights via vector quantization (VQ), which also reformulates decoding from GEMV to matrix multiplication, and applies 4:8-structured input sparsity to reduce bandwidth and memory demand. At the architecture level, every multiplication becomes a table lookup followed by a shallow adder tree, and the working set of a layer stays on the die. LUMOS achieves 37.7 TFLOPS/W and 9.59 MB/mm² effective on-die memory density, 1.91×–8.51× more energy-efficient than state-of-the-art DCIM macros. By holding a Qwen3-30B-A3B block on 38 cores, it decodes with zero off-chip weight traffic, 10.4× faster and 275× more energy-efficiently than the streaming VQ accelerator EVA on the same 2-bit model.
Read more
FlyCL: Memory-efficient Sparse Forward-only Continual Learning
Design, Automation & Test in Europe Conference (DATE) 2027
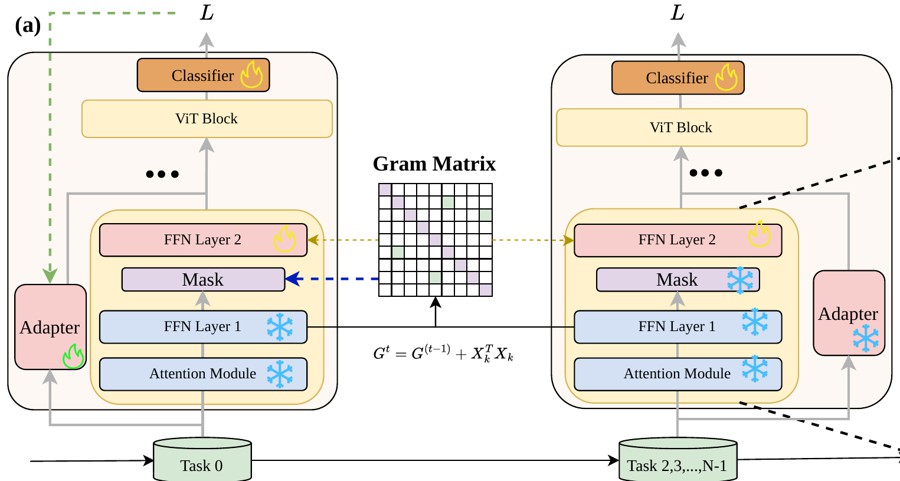
Continual learning (CL) enables AI models to incrementally adapt to new tasks, but remains challenging to deploy efficiently on edge platforms due to the high memory and computational demands of backpropagation. In this work, we propose FlyCL, the first memory-efficient, sparse, forward-only CL framework for pre-trained models (PTMs), which optimizes adapters purely through forward passes and updates the second multi-layer perceptron (MLP) projections and the classifier using closed-form solutions. For the first session, FlyCL computes the Gram matrix of the hidden activations, uses it to perform structured pruning on the backbone, and trains adapters with zeroth-order (ZO) optimization. For the next tasks, FlyCL updates the Gram matrix, the compensated projections, and the classifier in closed form to achieve task-specific adaptation. Extensive experiments show that FlyCL achieves up to 11.7× training memory reduction over state-of-the-art (SOTA) CL methods while pruning 30% of the backbone MLP channels; it stays within 0.8% of the most accurate baseline on CIFAR-100, surpasses it by 3.1% on ImageNet-R, and reduces the inference time by 17%–69%. On the same edge hardware with limited memory resources, FlyCL extends the maximum supported trainable model from ViT-base to a ∼3.6× larger ViT-large model, whereas traditional CL methods fail due to much larger memory requirements.
Read moreFlyCL: Memory-efficient Sparse Forward-only Continual Learning
Design, Automation & Test in Europe Conference (DATE) 2027
Continual learning (CL) enables AI models to incrementally adapt to new tasks, but remains challenging to deploy efficiently on edge platforms due to the high memory and computational demands of backpropagation. In this work, we propose FlyCL, the first memory-efficient, sparse, forward-only CL framework for pre-trained models (PTMs), which optimizes adapters purely through forward passes and updates the second multi-layer perceptron (MLP) projections and the classifier using closed-form solutions. For the first session, FlyCL computes the Gram matrix of the hidden activations, uses it to perform structured pruning on the backbone, and trains adapters with zeroth-order (ZO) optimization. For the next tasks, FlyCL updates the Gram matrix, the compensated projections, and the classifier in closed form to achieve task-specific adaptation. Extensive experiments show that FlyCL achieves up to 11.7× training memory reduction over state-of-the-art (SOTA) CL methods while pruning 30% of the backbone MLP channels; it stays within 0.8% of the most accurate baseline on CIFAR-100, surpasses it by 3.1% on ImageNet-R, and reduces the inference time by 17%–69%. On the same edge hardware with limited memory resources, FlyCL extends the maximum supported trainable model from ViT-base to a ∼3.6× larger ViT-large model, whereas traditional CL methods fail due to much larger memory requirements.
Read more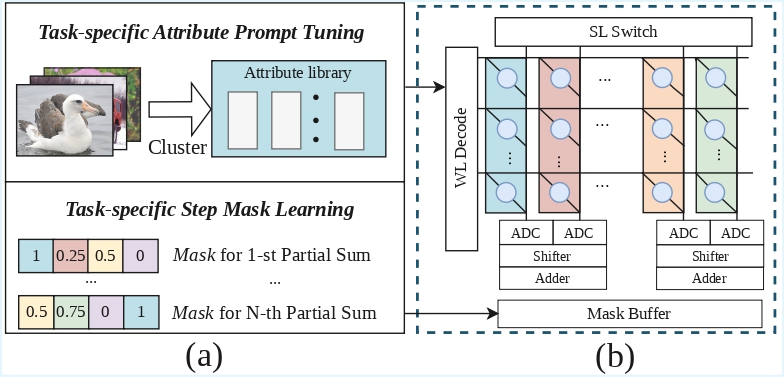
PRISM: A Programming-Free On-Device Multi-task Adaptation Framework for ReRAM-based Computing-in-Memory Accelerator
ACM/IEEE International Conference on Computer-Aided Design (ICCAD) 2026
Resistive random-access memory (ReRAM) crossbar arrays, known for high parallelism and energy efficiency, have been widely adopted to accelerate neural network (NN) inference. However, enabling on-device training on ReRAM-based accelerators remains challenging due to their high programming energy, voltage, and limited endurance. In this paper, we propose PRISM, a novel ReRAM programming-free on-device multi-task adaptation framework, enabling task adaptation via novel lightweight task-specific attribute prompt generation and step mask learning, with ultra-lightweight hardware and memory overhead, and eliminating energy-intensive ReRAM cell reprogramming. Specifically, PRISM first builds a task-specific attribute library using the frozen backbone model deployed in ReRAM by clustering representative features from a subset of the target new task dataset. Then, it computes the correlation between each input and the attribute library to generate a prefix prompt embedding. In addition, PRISM learns a novel crossbar column-wise and hardware-friendly step mask for each new task while keeping the backbone fixed. Extensive experiments show that the total training energy of PRISM is only 0.03% of that of all-parameter fine-tuning, with only 3.9% area overhead. Moreover, compared with the state-of-the-art multi-task adaptation method, PRISM improves accuracy by an average of 3.6% in the DeiT transformer model for standard multi-task adaptation datasets.
Read morePRISM: A Programming-Free On-Device Multi-task Adaptation Framework for ReRAM-based Computing-in-Memory Accelerator
ACM/IEEE International Conference on Computer-Aided Design (ICCAD) 2026
Resistive random-access memory (ReRAM) crossbar arrays, known for high parallelism and energy efficiency, have been widely adopted to accelerate neural network (NN) inference. However, enabling on-device training on ReRAM-based accelerators remains challenging due to their high programming energy, voltage, and limited endurance. In this paper, we propose PRISM, a novel ReRAM programming-free on-device multi-task adaptation framework, enabling task adaptation via novel lightweight task-specific attribute prompt generation and step mask learning, with ultra-lightweight hardware and memory overhead, and eliminating energy-intensive ReRAM cell reprogramming. Specifically, PRISM first builds a task-specific attribute library using the frozen backbone model deployed in ReRAM by clustering representative features from a subset of the target new task dataset. Then, it computes the correlation between each input and the attribute library to generate a prefix prompt embedding. In addition, PRISM learns a novel crossbar column-wise and hardware-friendly step mask for each new task while keeping the backbone fixed. Extensive experiments show that the total training energy of PRISM is only 0.03% of that of all-parameter fine-tuning, with only 3.9% area overhead. Moreover, compared with the state-of-the-art multi-task adaptation method, PRISM improves accuracy by an average of 3.6% in the DeiT transformer model for standard multi-task adaptation datasets.
Read more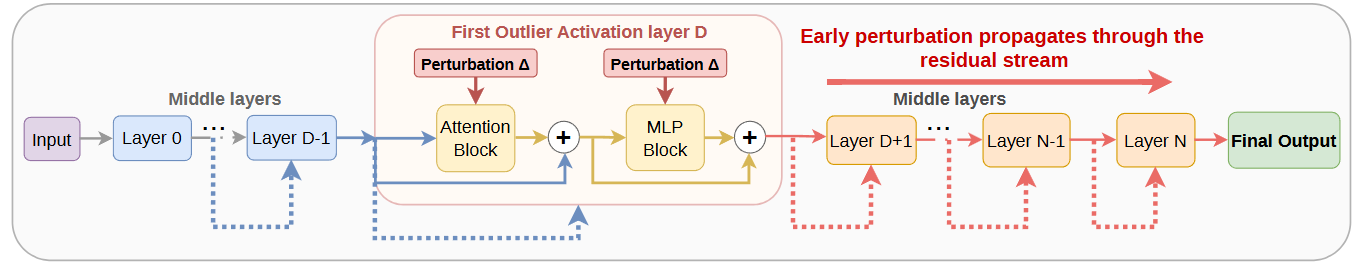
Dominant-Layer ZO: A Single Layer Dominates Zeroth-Order Fine-Tuning of LLMs
Conference on Neural Information Processing Systems (NeurIPS) 2026
Zeroth-order (ZO) optimization enables memory-efficient fine-tuning of large language models (LLMs) using only forward passes, but it remains unclear how useful adaptation is distributed across layers. In this work, we reveal a surprising phenomenon: ZO fine-tuning is sharply dominated by a single decoding layer. Across multiple LLM families and downstream tasks, fine-tuning this dominant layer alone consistently matches or even exceeds full-model ZO fine-tuning. We further show that the dominant layer is task-agnostic but model-specific, and can be identified before training through a simple inference-only analysis of activation outliers. Specifically, the dominant layer consistently aligns with the first activation-outlier layer in the pre-trained model. To explain this phenomenon, we analyze how perturbation effects propagate under ZO optimization. We find that the dominant layer combines two key properties: high perturbation sensitivity and early placement in the residual stream, allowing perturbation-induced effects to propagate and accumulate through remaining subsequent decoding layers. As a result, this layer produces disproportionately strong and stable optimization signals under forward-only updates. Extensive experiments on LLaMA2-7B and Qwen3-8B across nine benchmarks show that dominant-layer ZO fine-tuning improves average performance over full-model MeZO and LoRA-based ZO fine-tuning while achieving up to 4.52 training speedup.
Read more
Dominant-Layer ZO: A Single Layer Dominates Zeroth-Order Fine-Tuning of LLMs
Conference on Neural Information Processing Systems (NeurIPS) 2026
Zeroth-order (ZO) optimization enables memory-efficient fine-tuning of large language models (LLMs) using only forward passes, but it remains unclear how useful adaptation is distributed across layers. In this work, we reveal a surprising phenomenon: ZO fine-tuning is sharply dominated by a single decoding layer. Across multiple LLM families and downstream tasks, fine-tuning this dominant layer alone consistently matches or even exceeds full-model ZO fine-tuning. We further show that the dominant layer is task-agnostic but model-specific, and can be identified before training through a simple inference-only analysis of activation outliers. Specifically, the dominant layer consistently aligns with the first activation-outlier layer in the pre-trained model. To explain this phenomenon, we analyze how perturbation effects propagate under ZO optimization. We find that the dominant layer combines two key properties: high perturbation sensitivity and early placement in the residual stream, allowing perturbation-induced effects to propagate and accumulate through remaining subsequent decoding layers. As a result, this layer produces disproportionately strong and stable optimization signals under forward-only updates. Extensive experiments on LLaMA2-7B and Qwen3-8B across nine benchmarks show that dominant-layer ZO fine-tuning improves average performance over full-model MeZO and LoRA-based ZO fine-tuning while achieving up to 4.52 training speedup.
Read more
Harmony: A Hardware-Mapping Co-Exploration Framework for Hybrid CIM-based Vision Transformer Accelerator
International Symposium on Quality Electronic Design (ISQED) 2026
🏆 Best Paper Award
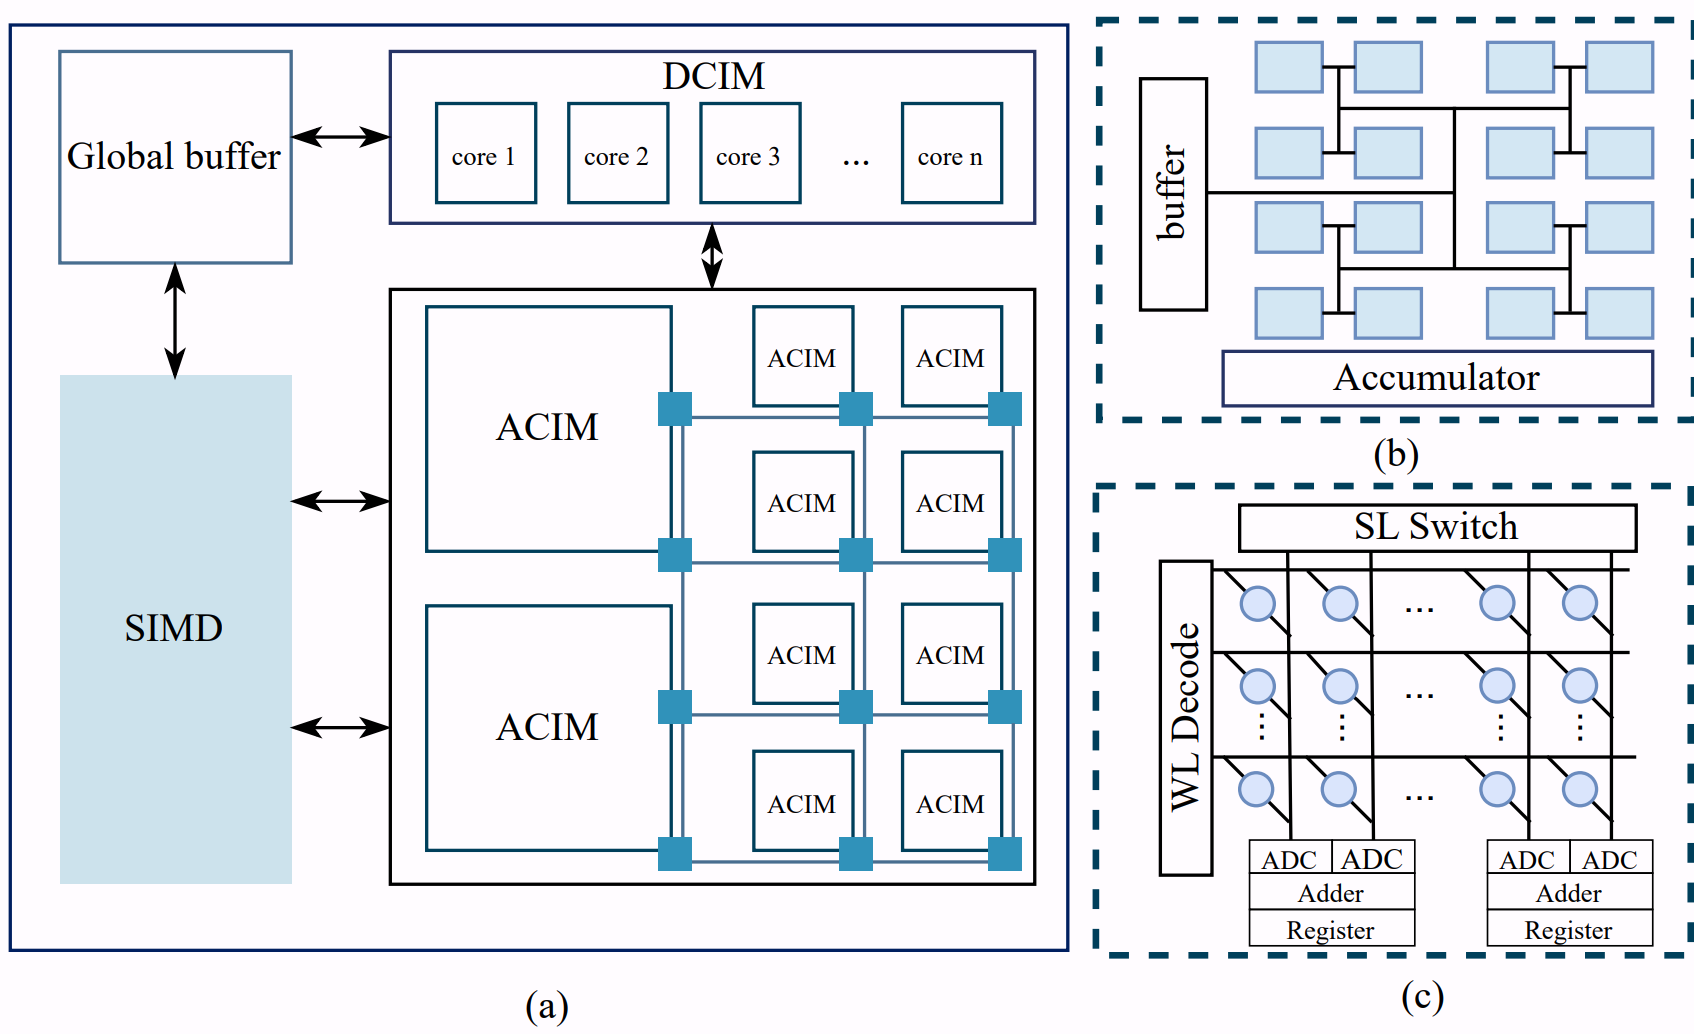
Computing-in-memory (CIM) architectures have successfully enhanced convolutional neural network (CNN) performance, but the automation of high-performance CIM-based transformer accelerators is still challenging. Specifically, the design space of hardware design and mapping is extremely large due to the complex model structure and data flow. To address this problem, we propose Harmony, a hardware and mapping co-exploration framework to optimize the hybrid CIM-based vision transformer accelerator. We define a universal design space representation for implementing vision transformers in CIM-based accelerators that support hybrid and heterogeneous features. The corresponding design space comprises the hardware configuration of CIM macros and their spatial mapping scheme. Furthermore, we propose the knowledge-guided grid search (KGGS) algorithm and improved genetic algorithm (IGA) to boost exploration efficiency. The orthogonal experiment and dominance analysis of KGGS could obtain the exploration probabilities of different parameters and ensure its stability, while the unique order crossover and swapping mutation of IGA could retain relative order to avoid legalization processes during the iteration.
Read moreHarmony: A Hardware-Mapping Co-Exploration Framework for Hybrid CIM-based Vision Transformer Accelerator
International Symposium on Quality Electronic Design (ISQED) 2026
🏆 Best Paper Award
Computing-in-memory (CIM) architectures have successfully enhanced convolutional neural network (CNN) performance, but the automation of high-performance CIM-based transformer accelerators is still challenging. Specifically, the design space of hardware design and mapping is extremely large due to the complex model structure and data flow. To address this problem, we propose Harmony, a hardware and mapping co-exploration framework to optimize the hybrid CIM-based vision transformer accelerator. We define a universal design space representation for implementing vision transformers in CIM-based accelerators that support hybrid and heterogeneous features. The corresponding design space comprises the hardware configuration of CIM macros and their spatial mapping scheme. Furthermore, we propose the knowledge-guided grid search (KGGS) algorithm and improved genetic algorithm (IGA) to boost exploration efficiency. The orthogonal experiment and dominance analysis of KGGS could obtain the exploration probabilities of different parameters and ensure its stability, while the unique order crossover and swapping mutation of IGA could retain relative order to avoid legalization processes during the iteration.
Read more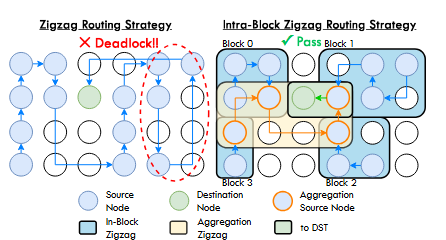
Optimizing Heterogeneous Compute-in-Memory with Hybrid Dataflow and In-Network Reduction for Vision Transformer
International Symposium on Low Power Electronics and Design (ISLPED) 2025
Vision Transformers (ViTs) have shown remarkable success in computer vision tasks, but their computational demands pose significant challenges for efficient deployment. This paper presents an optimization framework for heterogeneous Compute-in-Memory (CIM) architectures that leverages hybrid dataflow and in-network reduction techniques to accelerate ViT inference. Our approach addresses the unique computational patterns of ViTs by combining different dataflow strategies and implementing efficient reduction operations within the CIM network.
Read moreOptimizing Heterogeneous Compute-in-Memory with Hybrid Dataflow and In-Network Reduction for Vision Transformer
International Symposium on Low Power Electronics and Design (ISLPED) 2025
Vision Transformers (ViTs) have shown remarkable success in computer vision tasks, but their computational demands pose significant challenges for efficient deployment. This paper presents an optimization framework for heterogeneous Compute-in-Memory (CIM) architectures that leverages hybrid dataflow and in-network reduction techniques to accelerate ViT inference. Our approach addresses the unique computational patterns of ViTs by combining different dataflow strategies and implementing efficient reduction operations within the CIM network.
Read more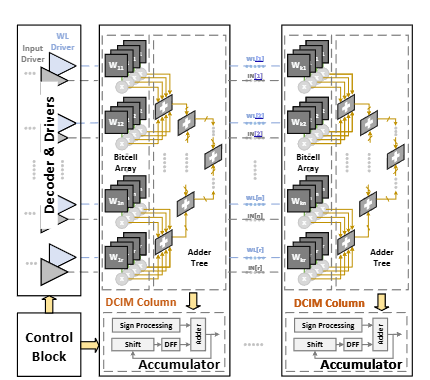
OpenC2: An Open-Source End-to-End Hardware Compiler Development Framework for Digital Compute-in-Memory Macro
Design, Automation & Test in Europe Conference (DATE) 2024
Compute-in-Memory (CIM) has emerged as a promising paradigm to address the memory wall problem in modern computing systems. However, the lack of comprehensive toolchains for CIM macro development hinders its widespread adoption. This paper presents OpenC2, an open-source end-to-end hardware compiler development framework specifically designed for digital CIM macros. OpenC2 provides a complete toolchain from high-level algorithm descriptions to optimized CIM macro implementations, enabling rapid prototyping and design space exploration.
Read moreOpenC2: An Open-Source End-to-End Hardware Compiler Development Framework for Digital Compute-in-Memory Macro
Design, Automation & Test in Europe Conference (DATE) 2024
Compute-in-Memory (CIM) has emerged as a promising paradigm to address the memory wall problem in modern computing systems. However, the lack of comprehensive toolchains for CIM macro development hinders its widespread adoption. This paper presents OpenC2, an open-source end-to-end hardware compiler development framework specifically designed for digital CIM macros. OpenC2 provides a complete toolchain from high-level algorithm descriptions to optimized CIM macro implementations, enabling rapid prototyping and design space exploration.
Read more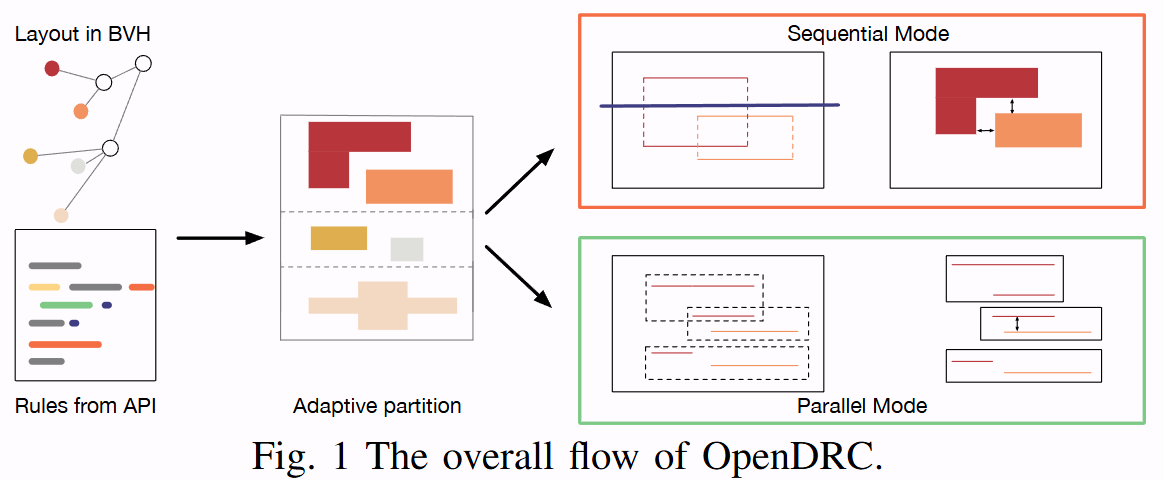
OpenDRC: An Efficient Open-Source Design Rule Checking Engine with Hierarchical GPU Acceleration
ACM/IEEE Design Automation Conference (DAC) 2023
Design Rule Checking (DRC) is a critical step in the VLSI design flow that ensures manufacturability of integrated circuits. Traditional DRC tools face scalability challenges with increasing design complexity. This paper presents OpenDRC, an efficient open-source DRC engine that leverages hierarchical GPU acceleration to achieve significant performance improvements. Our approach utilizes the parallel processing capabilities of GPUs and hierarchical design representation to accelerate DRC operations while maintaining accuracy.
Read moreOpenDRC: An Efficient Open-Source Design Rule Checking Engine with Hierarchical GPU Acceleration
ACM/IEEE Design Automation Conference (DAC) 2023
Design Rule Checking (DRC) is a critical step in the VLSI design flow that ensures manufacturability of integrated circuits. Traditional DRC tools face scalability challenges with increasing design complexity. This paper presents OpenDRC, an efficient open-source DRC engine that leverages hierarchical GPU acceleration to achieve significant performance improvements. Our approach utilizes the parallel processing capabilities of GPUs and hierarchical design representation to accelerate DRC operations while maintaining accuracy.
Read more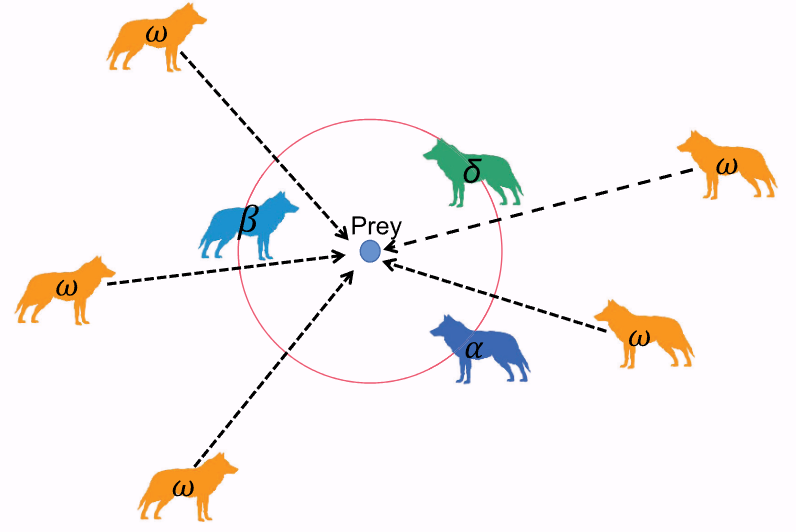
Symmetrical indoor visible light layout optimized by a modified grey wolf algorithm
Applied Optics (AO) 2022
Visible light communication (VLC) systems require optimal LED placement to ensure uniform illumination and reliable communication. This paper presents a modified grey wolf optimization algorithm for designing symmetrical indoor visible light layouts. The proposed approach optimizes LED positioning to achieve balanced illumination distribution while maintaining communication quality, addressing the challenges of indoor VLC system design.
Read moreSymmetrical indoor visible light layout optimized by a modified grey wolf algorithm
Applied Optics (AO) 2022
Visible light communication (VLC) systems require optimal LED placement to ensure uniform illumination and reliable communication. This paper presents a modified grey wolf optimization algorithm for designing symmetrical indoor visible light layouts. The proposed approach optimizes LED positioning to achieve balanced illumination distribution while maintaining communication quality, addressing the challenges of indoor VLC system design.
Read more